Visual
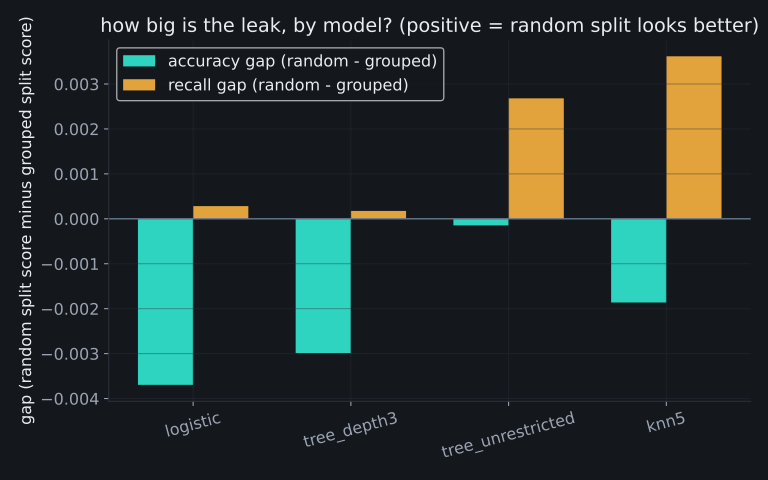
s1-3 showed the leak exists for one model. How big is it, and does it depend on the model? Re-run logistic
regression, a depth-3 tree, an unrestricted tree, and k-NN under random vs. patient-grouped splits. Table the
recall/accuracy gaps. Then: is number_inpatient doing the recognising? Drop it and re-run.
Dropping number_inpatient from the unrestricted tree drops recall substantially (0.1632 →
0.1337 on the random split) even though the leak gap for that model stays small either way. Reading:
number_inpatient carries real predictive signal about future readmission risk, not just
patient-identity leakage — the leak this dataset/model combination exhibits is small in size, even though it
is real in kind (confirmed directly: 8,037 of 22,402 test patients in a random split also appear in train).
Open mini-project.ipynb to reproduce it yourself.
This marks "leakage" as touched in your progress tracker. It does not gate module mastery — Project A's six checkpoints are the only requirement for "project complete."